AI Models
GPT-6 Sol and Luna Explained: Price, Performance, and Who Should Use Each
OpenAI split GPT-6 into a powerful work model and a low-cost high-volume model. Here is how Sol and Luna differ in practice.
One model family, two very different operating points
OpenAI's GPT-6 Sol and GPT-6 Luna make the model-selection decision unusually explicit. Sol is the stronger general work model, aimed at coding, agents, computer use, and tasks where a mistake or an extra retry is expensive. Luna is optimized for speed and volume, with pricing low enough to make model calls viable inside products that process large quantities of text. They share a generation, but they should not be treated as interchangeable quality tiers.
At launch, standard API pricing was listed at $2 per million input tokens and $10 per million output tokens for Sol. Luna was listed at $0.10 per million input tokens and $0.50 per million output tokens. OpenAI described both as 50 percent below the promotional prices of their GPT-5.6 predecessors. Cached input can reduce repeated-context costs further. Those prices are only one part of the bill because tool use, search, storage, retries, and engineering overhead can dominate a real agent workflow.
What Sol is designed to do
Sol is the default candidate when the work requires deeper reasoning, reliable code changes, or interaction with software. OpenAI reports improved factuality over GPT-5.6 Sol and strong internal results across coding and computer-use evaluations. Its published DeepSWE result of 68.8 percent sits close to the strongest competing frontier systems in OpenAI's comparison. These are vendor-selected measurements, so they are useful signals rather than a guarantee for every repository or task.
For teams, Sol's advantage is less about winning a single benchmark and more about reducing expensive failure loops. A model that completes a repository task in one attempt may cost less overall than a cheaper model that needs multiple retries, human intervention, and damaged state cleanup. Sol therefore suits complex feature implementation, migration planning, browser operations, research synthesis, and customer-facing analysis where the answer needs to survive review.
Where Luna becomes compelling
Luna targets workloads where latency and unit cost matter more than extracting the last percentage point of capability. Summarization, classification, tagging, simple retrieval-augmented answers, content moderation triage, and first-pass document processing can involve millions of calls. At that scale, Luna's price changes the product economics. It can also serve as the fast front layer of an agent, escalating only difficult inputs to Sol or another frontier model.
Cheap does not mean universally safe. A small per-call price can hide poor routing, unnecessary context, and uncontrolled retries. Teams should measure the accepted-answer cost rather than the raw token cost. If Luna resolves 90 percent of routine cases and accurately identifies the remaining 10 percent for escalation, it can be excellent. If it confidently mishandles rare but consequential requests, the apparent savings may disappear in support work or risk exposure.
A routing strategy that uses both
The strongest pattern is to separate tasks before choosing the model. Use deterministic filters for exact rules and sensitive permissions. Send high-volume, low-complexity work to Luna. Route complex instructions, large code changes, multi-source analysis, and computer interaction to Sol. Add escalation triggers based on uncertainty, missing data, repeated tool failures, and the value of the action. Keep a human approval step for payments, deletions, legal decisions, and irreversible external changes.
Prompt caching also matters. OpenAI says cached input reads receive a 90 percent discount. Stable system instructions, schemas, and large reference blocks can therefore be structured so they remain cacheable across calls. That requires disciplined context design. Constantly reordering instructions or injecting volatile data into the beginning of the prompt can destroy cache reuse. A good router considers context shape and tool costs, not only the name on the model.
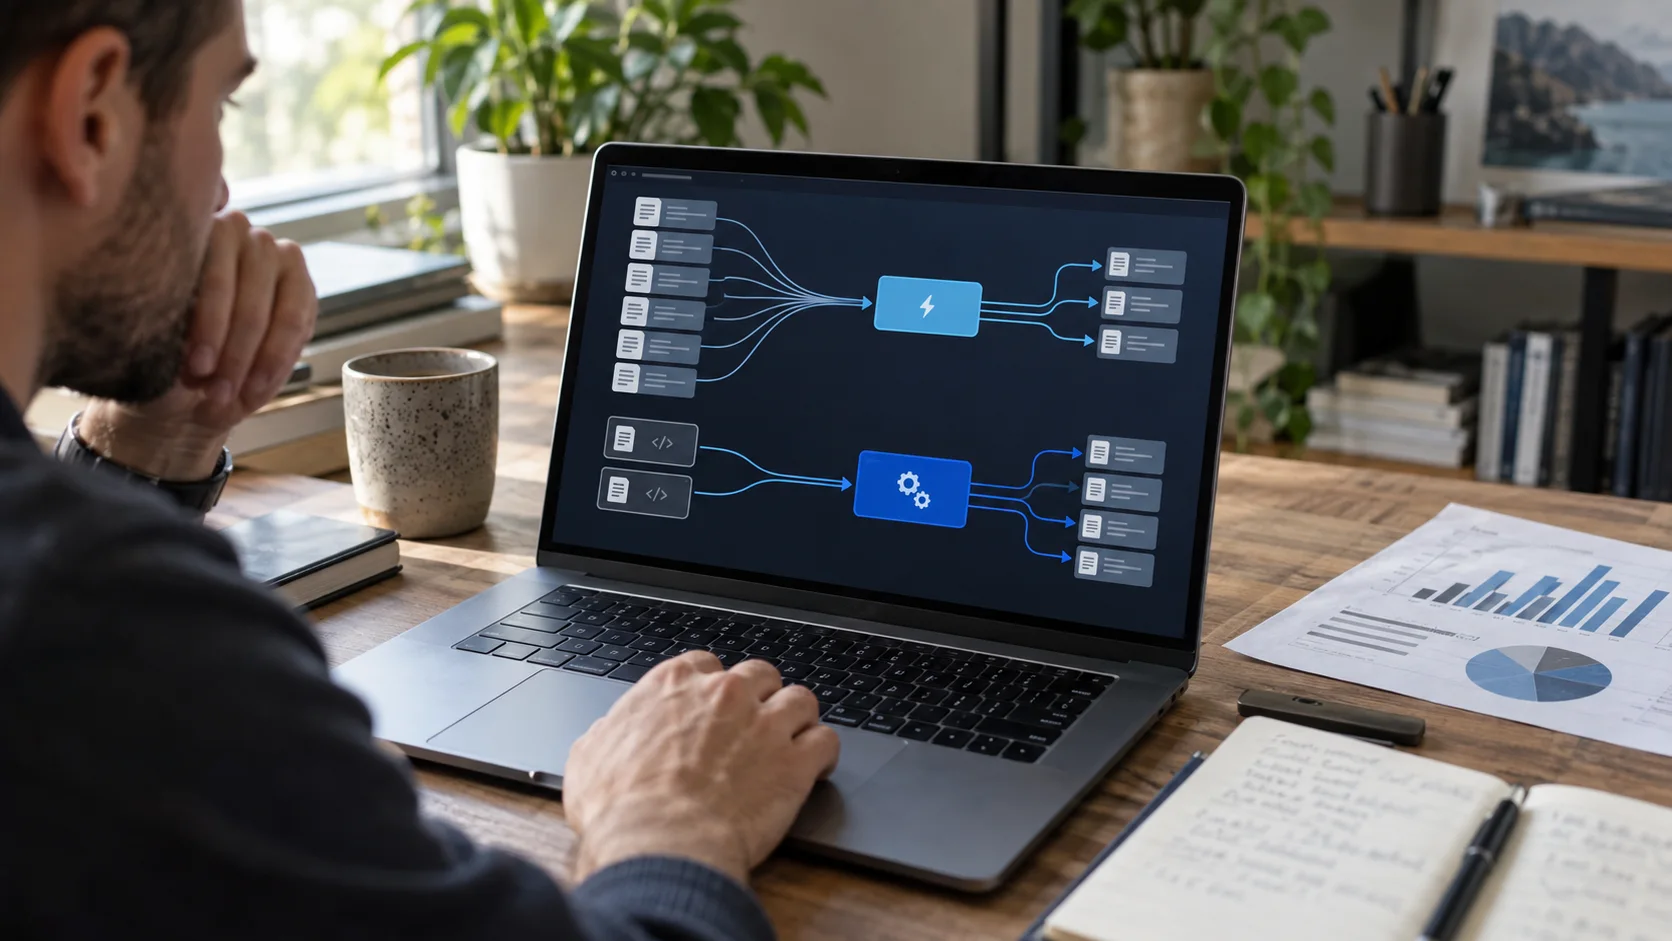
How to choose for your own workload
Build a private evaluation set from real tasks before migrating. Score correctness, completeness, latency, tool-call reliability, tokens consumed, and the amount of human editing required. Test both normal and adversarial inputs. For coding, measure whether tests pass and whether the patch creates regressions. For support, measure resolution quality and escalation accuracy. For data extraction, measure fields independently rather than accepting a single aggregate score.
Choose Luna when it meets the quality threshold with a comfortable margin. Choose Sol when the cost of a weak answer exceeds the token savings, or when the task benefits from its tool and computer-use strengths. Revisit the routing rules as prices and models change. GPT-6 is not a reason to replace every model overnight. It is a reason to make model selection an explicit, measured part of application architecture.
The first migration should be reversible
Run the new route in shadow mode before moving customer traffic. Record what Sol and Luna would have answered alongside the current system, then compare outcomes without exposing users to an untested change. Move a small percentage of low-risk requests first and keep the old path available as a fallback. This approach catches differences in formatting, tool behavior, and rate limits that a static benchmark misses. It also gives finance and engineering a real cost baseline before the migration becomes difficult to unwind.