AI Models
Jev AI vs LLMs: When a Decision Model Is the Better Choice
Jev and large language models solve different problems. This guide shows when to use a decision model, an LLM, deterministic code, or all three.
The comparison starts with the output you need
Comparing Jev with a large language model as if one must replace the other misses the architectural point. General-purpose LLMs are designed to generate flexible language and solve open-ended tasks. Jev is designed to select among bounded outcomes and express uncertainty around that selection. The right question is not which model is smarter. It is whether the next component in your system needs prose, code, analysis, a tool call, or a small typed decision.
If a user asks for a contract summary, a product description, or a debugging explanation, an LLM is the natural fit. If an application asks whether a message is urgent, which queue should receive it, or whether an agent should retry a failed step, a decision model may be the cleaner fit. If the answer follows an explicit and stable policy, neither is ideal. Deterministic code gives a result that is cheaper, faster, and easier to audit.
Where general-purpose LLMs remain stronger
Large models handle ambiguity by producing a rich response. They can combine evidence, explain tradeoffs, ask a clarifying question, write software, and adapt the format to a user's request. That flexibility matters in research, customer conversations, creative work, and complex agent tasks. It also lets one model cover many low-volume use cases before a team knows which workflows deserve specialized infrastructure.
The same flexibility creates operational friction in narrow decision paths. A model may return extra commentary, invent a category, or follow an instruction embedded inside untrusted content. Structured-output features reduce these problems, but the team still pays for the capabilities and token volume of a broad model. A decision model starts from a more constrained contract. That can make the surrounding code smaller and the behavior easier to test, provided that the decision itself is genuinely bounded.
Where Jev has an architectural advantage
Jev exposes choices, scores, booleans, and probabilities as first-class outputs. This is useful when application logic needs to branch immediately. A router can inspect the selected route and its probability without extracting a label from prose. A workflow controller can decide whether to continue, retry, or escalate. A risk system can combine a model score with deterministic limits rather than treating a generated explanation as the final answer.
The narrower interface also encourages better measurement. Teams can build confusion matrices, inspect calibration, choose class-specific thresholds, and trace business outcomes back to model decisions. None of those practices are impossible with an LLM, but they are easier to neglect when the output is free-form. Jev makes the contract visible. It does not remove the need for evaluation, and it cannot make an underspecified business rule precise on its own.
The hybrid pattern is usually more useful than a winner
A strong production design often uses multiple layers. Deterministic code first handles known rules, permissions, hard limits, and exact matches. Jev then handles bounded ambiguity, such as choosing a route from context or deciding whether a workflow has enough evidence to continue. A capable LLM is reserved for steps that require synthesis, generation, or deeper reasoning. Humans review cases where confidence is low or the consequence is high.
Consider a support system. Code can recognize account ownership and service entitlements. Jev can classify the request, estimate urgency, and select a queue. An LLM can draft a response using retrieved account data. A human can approve refunds or security actions. This layered design reduces cost without pretending that the smallest model can do everything. It also limits the blast radius when any one model fails.
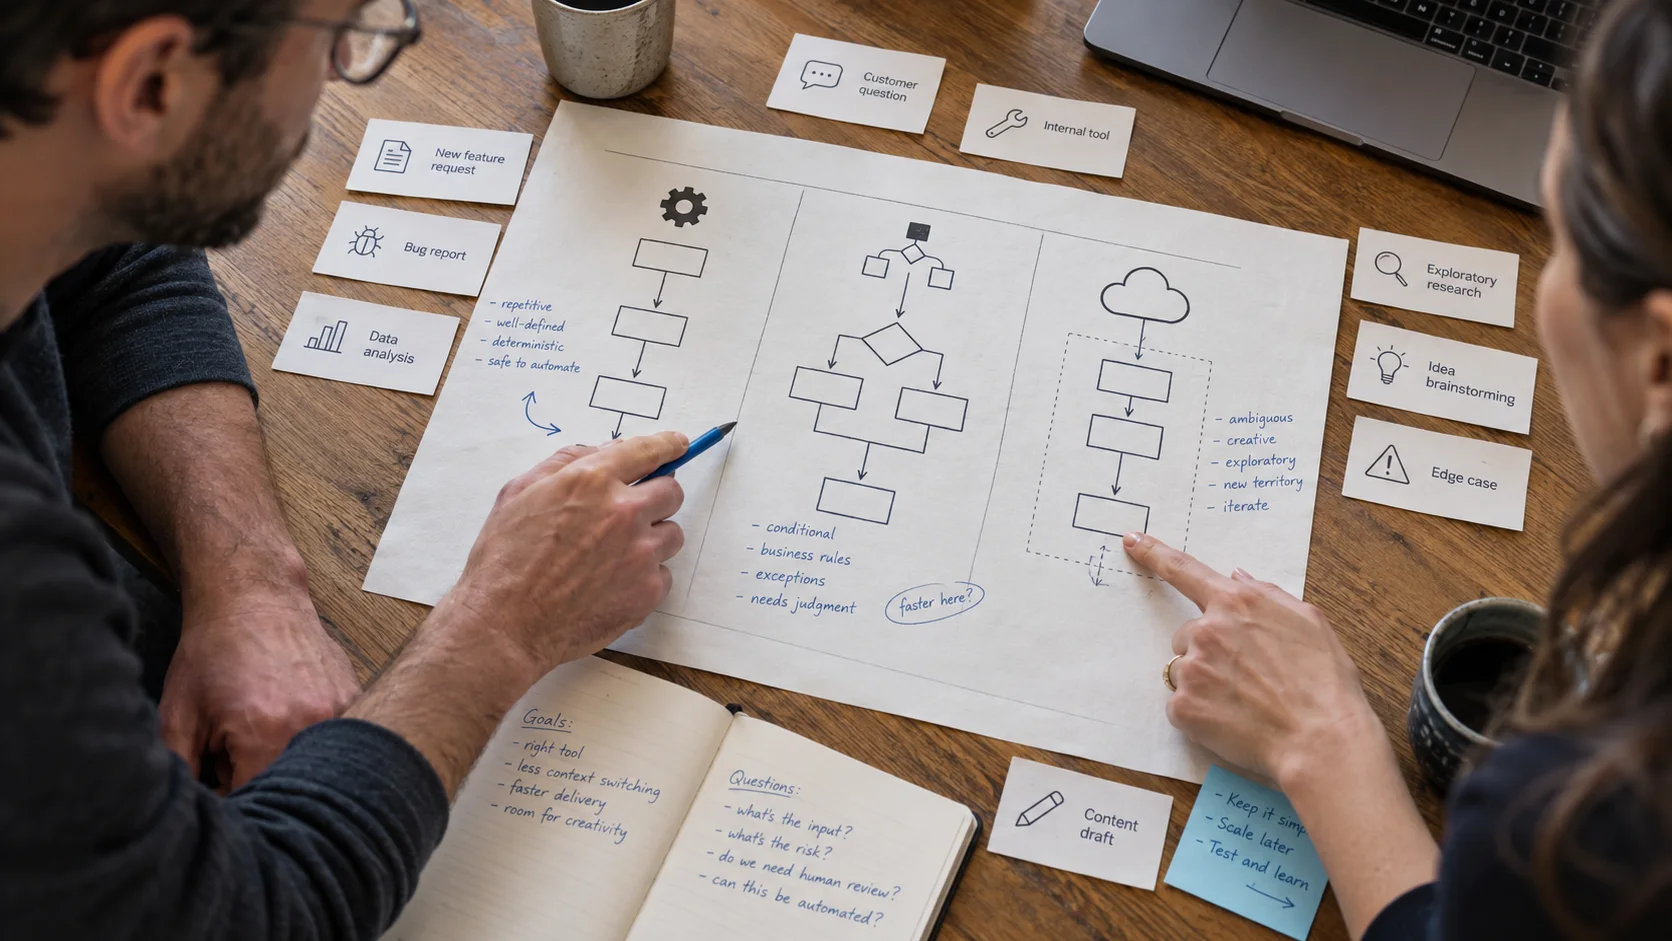
How to choose without following the hype
Write down the allowed outputs, acceptable latency, decision frequency, error costs, and evidence required for an audit. If the output space cannot be stated clearly, Jev is probably premature. If the decision can be expressed as a stable rule, use code. If the task needs a novel artifact or multi-step reasoning, test a general-purpose LLM. If it needs a repeated judgment among known outcomes, evaluate a decision model against the existing baseline.
Do not select Jev because its early adoption chart is dramatic, and do not keep an expensive LLM merely because it already works. Run both on a representative dataset. Measure not only accuracy but calibration, class imbalance, latency at peak load, provider reliability, and the cost of verification. The most efficient system is not the one with the cheapest model call. It is the one that reaches an acceptable outcome with the least total operational risk.
The decision model category is still early
Jev's launch may create a broader category of models trained and priced specifically for judgment under constraints. Expect providers to compete on calibration, latency, private deployment, and integrations with workflow engines. The open question is whether specialized models remain meaningfully better after general-purpose models improve their own structured outputs. Teams can protect themselves from that uncertainty by defining an internal decision interface and testing several backends behind it. The durable asset is the evaluation data and policy logic, not a permanent dependency on one model name.