AI Trends
Open-Weight AI Models Now Run Most Gateway Tokens. Here Is What Changed
Open-weight models reached 56 percent of Vercel AI Gateway token volume in August. Cost, routing, and better smaller models explain the shift.
The production mix changed faster than the model leaderboard
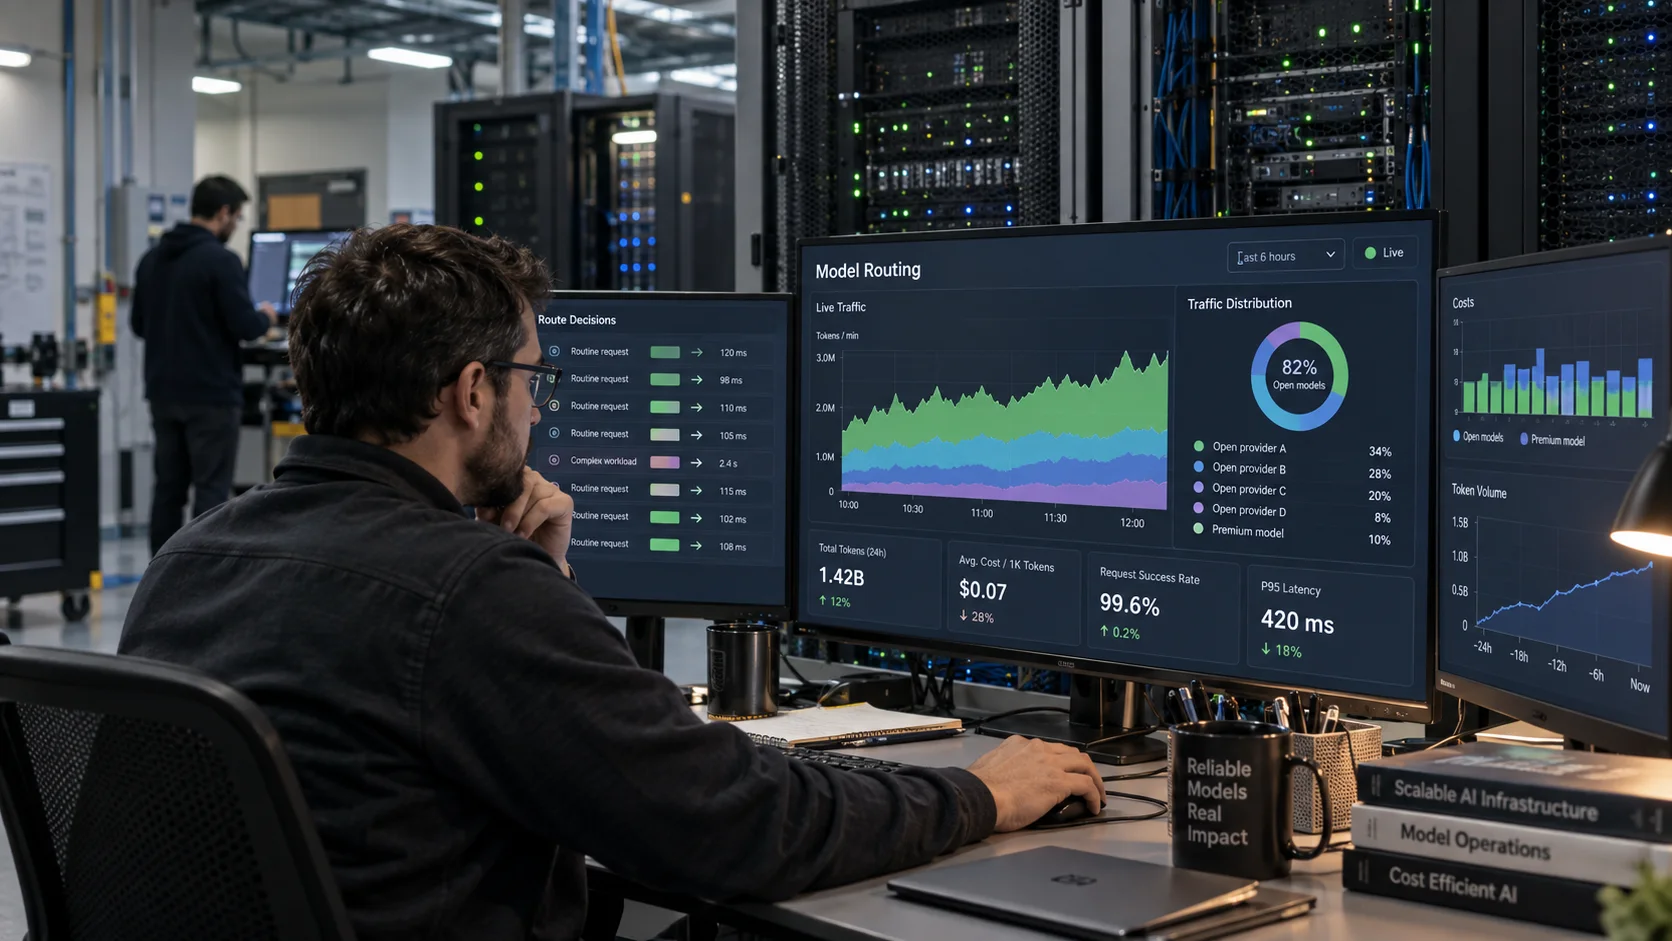
Vercel's September 2026 AI Gateway Production Index reported that open-weight models represented 56 percent of token volume in August, up from 7 percent in December. Those models accounted for only 14 percent of spend, and average price per token across the gateway fell 23.2 percent during August. This is one platform's anonymized aggregate traffic, not a census of the entire industry, but the direction is significant. Production teams are increasingly selecting models by workload rather than sending everything to one premium provider.
Open weight means the model parameters are available under a license that allows some level of download, hosting, or modification. It does not necessarily mean fully open-source training data, code, or unrestricted commercial use. Licensing terms vary and can change the deployment decision. The operational trend is broader: competitive models can now be served by multiple providers, hosted privately, or routed through gateways at prices that make high-volume use practical.
Why token volume moved before spending did
High-volume workloads are often the least glamorous. Classification, extraction, summarization, moderation, translation, and retrieval responses may use huge numbers of tokens without requiring frontier reasoning. Open-weight models have become good enough for many of these tasks. Because their token prices are lower, they can carry a majority of volume while representing a much smaller share of spend.
That does not imply that closed frontier models are disappearing. They remain valuable for difficult coding, research, computer use, and complex agent behavior. A modern application may use an open model for routine requests and a premium model for escalation. The result is a barbell: large token volume at low cost on one side, smaller but expensive high-value work on the other. Averages obscure that division.
Gateways make model switching operationally possible
A gateway gives applications a common interface across providers and models, along with routing, observability, spend controls, and fallbacks. Without that layer, changing a model can require new credentials, request formats, streaming behavior, and error handling. With it, teams can evaluate candidates against the same traces and gradually shift traffic. This infrastructure is one reason model adoption can move quickly after a release.
The abstraction is not perfect. Providers differ in tokenization, structured output, safety filters, context limits, tool calling, and data policies. A model name behind two providers may still behave differently because serving stacks and quantization choices vary. Teams should preserve provider-specific tests and avoid assuming that a common API makes results identical. Portability reduces switching cost, not evaluation work.
Self-hosting is about control, not automatic savings
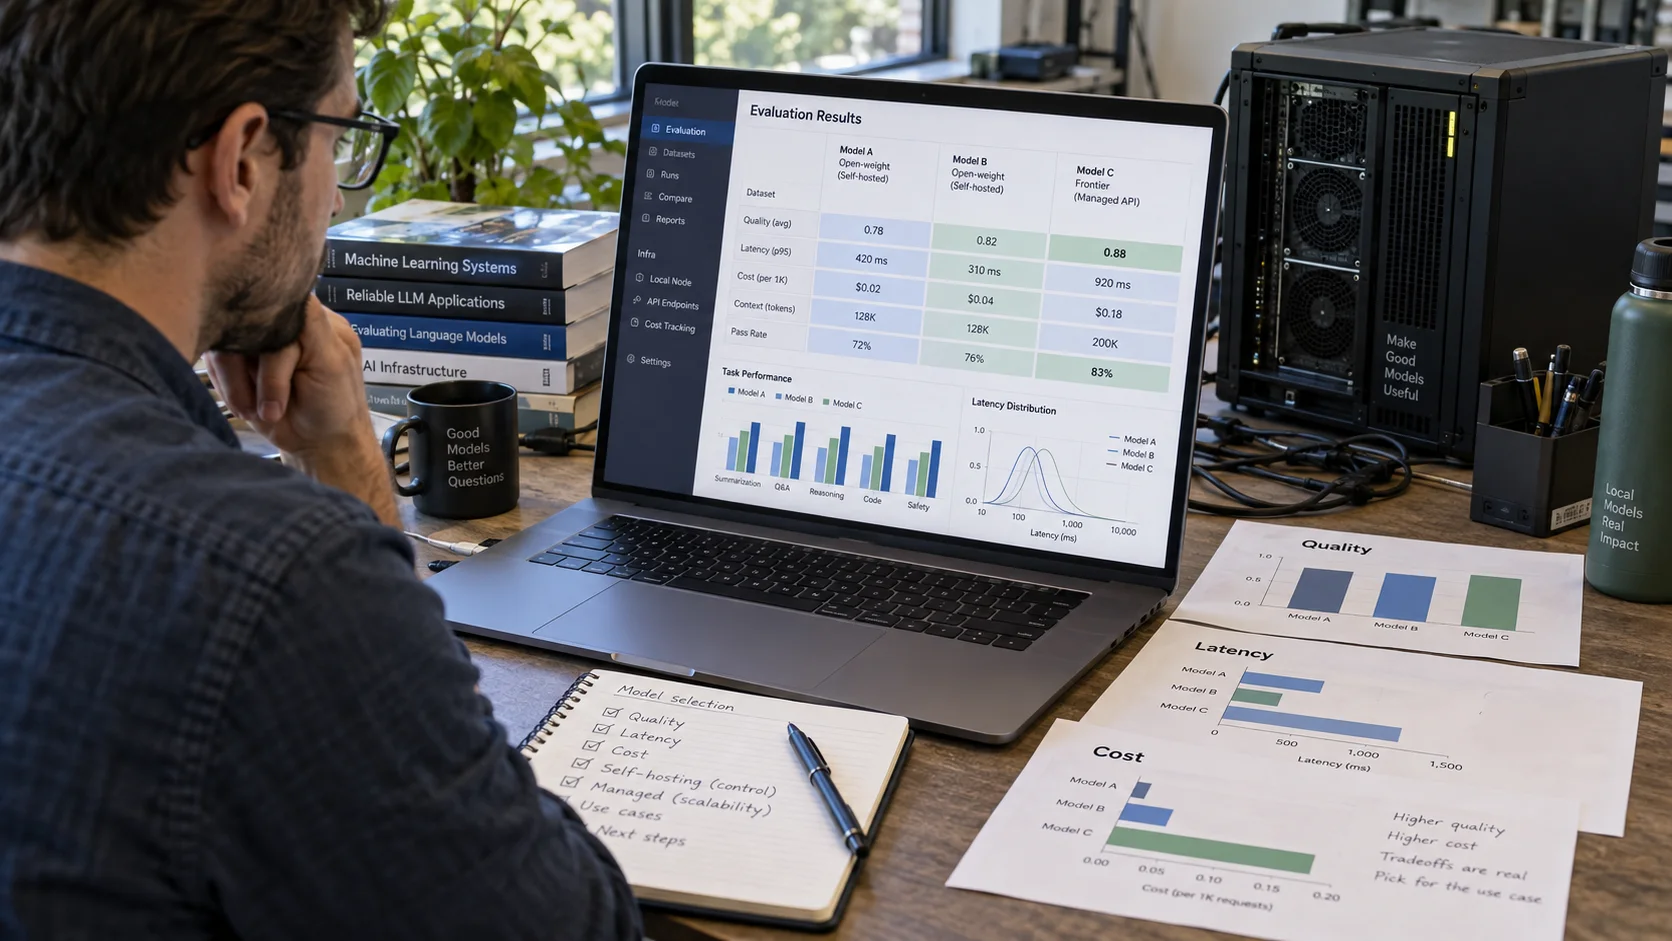
Open weights allow private deployment, which can improve data control, latency in a specific region, customization, or resilience. It can also add GPU provisioning, autoscaling, model optimization, monitoring, security patching, and on-call responsibility. Low utilization makes dedicated infrastructure expensive. Managed providers often remain cheaper for variable workloads because they spread hardware costs across customers.
A serious comparison includes engineering time, capacity buffers, failure recovery, and the opportunity cost of operating inference. Self-hosting is strongest when traffic is steady, privacy requirements are strict, specialized tuning creates business value, or provider independence is strategic. It is weak when a small team chooses it only to avoid a visible API price while ignoring the hidden platform burden.
What teams should do with the trend
Create a workload map. Separate routine generation, extraction, classification, code, search, and high-consequence decisions. Build evaluation sets from production examples and measure each candidate on quality, latency, price, failure behavior, and provider reliability. Route to the least expensive model that clears the required quality threshold, then keep an escalation path for hard cases. Re-evaluate regularly because the frontier and the price curve move quickly.
Do not adopt an open model to satisfy an ideological preference, and do not dismiss it because a flagship closed model wins a broad benchmark. The production data suggests that specialization and routing are already normal. The strategic skill is no longer choosing one model for a year. It is maintaining a measured model portfolio without letting the application become dependent on untested, constantly changing behavior.
Interpret gateway statistics carefully
Vercel notes that its index is based on anonymized gateway traffic and that classifications can change as the market evolves. Its users may not represent banks, consumer chat products, governments, or companies with private inference clusters. Token share is also not task share because long-context workloads can dominate volume. Use the report as evidence of a strong production shift, then validate the pattern against your own traffic and constraints rather than presenting 56 percent as a universal market share figure. Spend share, request count, active teams, and business value can each tell a different story.