AI Trends
What Is Jev AI? Inside the Decision Model That Went Viral With Developers
Jev is not another chatbot. It is a compact decision model built to turn messy context into typed choices, scores, and probabilities.
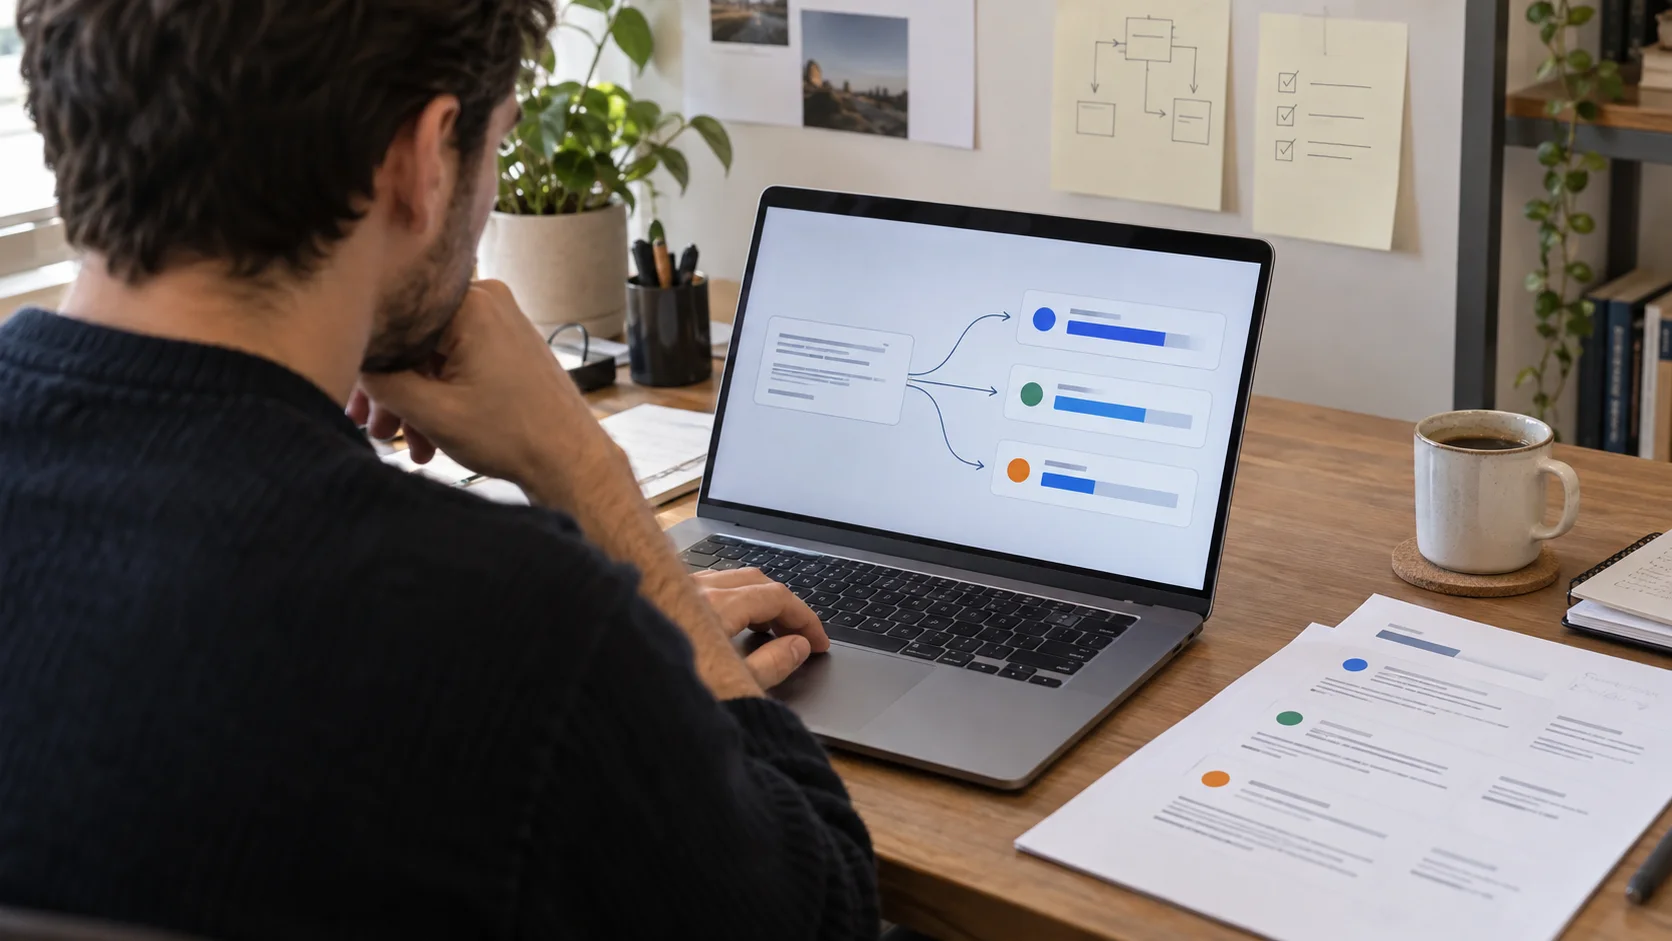
Jev is a decision model, not a general-purpose chatbot
Jev AI became one of September 2026's most discussed developer models because it tackles a narrow problem that large language models often handle inefficiently. Instead of writing an essay, generating code, or holding a conversation, Jev takes structured context and returns a constrained decision. The output can be a choice, a score, or a boolean, accompanied by probabilities that show how strongly the model favors each outcome. That makes it useful in software paths where a system needs to decide what happens next, not explain the entire world.
A typical input might include a support ticket, account tier, recent activity, and a small set of policy facts. Jev can then choose between routes such as billing, technical support, or account security. Another workflow might ask whether an automated process should continue, retry, escalate, or stop. The point is not that a decision model has perfect judgment. The point is that its interface matches the job. A developer receives a typed result that is easier to validate, measure, and connect to application logic than a paragraph that must be parsed after generation.
Why the launch spread so quickly
Vercel reported that Jev reached nearly 13 percent of paid AI Gateway teams within its first 24 hours, making it the gateway's fastest-adopted model at launch. That number describes adoption within Vercel's own paid gateway customer base, not the entire AI market, but it still reveals a real appetite. Teams are looking for smaller models that can sit inside high-volume production workflows without paying frontier-model prices for every classification or routing step.
TypeSafe, the company behind Jev, also published internal evaluations claiming large speed and cost advantages in its target workflows. Those figures should be treated as vendor-reported results, not universal benchmarks. Latency, accuracy, and price depend on the prompt, the competing model, network overhead, and the consequences of a wrong decision. The more durable insight is that builders are separating decision work from generation work. A single large model no longer needs to handle every step in an application.
How typed choices and probabilities change the workflow
Typed outputs are valuable because they narrow the space of possible responses. If a workflow permits only approve, reject, or review, the application can refuse anything outside those values before it reaches a sensitive action. Probabilities add another control layer. A team might automatically accept a route above 0.92 confidence, send results between 0.65 and 0.92 to a cheaper verification step, and require human review below 0.65. Those thresholds can be tuned using real outcomes rather than intuition.
This is also where teams can make a dangerous assumption. A valid schema does not make a decision correct. Jev's own explainer emphasizes that typed output guarantees shape, not semantic truth. If the model confidently misreads context, the application still receives a perfectly formed wrong answer. Good implementation therefore requires a labeled evaluation set, calibration checks, fallbacks, logs, and an explicit human path for decisions involving money, safety, employment, healthcare, or access rights.
Where Jev fits best
The strongest early use cases are frequent, bounded, and reversible. Request routing, lead qualification, moderation triage, alert prioritization, retry decisions, and selecting the next tool in an agent workflow all fit that pattern. The possible outcomes are known in advance, the system can record whether each decision worked, and a mistake can often be corrected without lasting harm. Jev can also answer several related questions in parallel, which is useful when one input needs a risk score, a route, and an escalation flag at the same time.
Jev is a poor fit when the real task is exploration, explanation, creative synthesis, or complex reasoning across uncertain evidence. It should not replace a domain expert simply because it returns probabilities. A probability is a model estimate, not a guarantee and not a legal justification. Teams should also resist turning a complicated policy into dozens of opaque model calls when ordinary deterministic code would be clearer. If a rule can be written and maintained as a rule, code remains the more predictable tool.
A practical evaluation checklist
Start with one decision that already has historical outcomes. Define the permitted choices and the cost of false positives and false negatives before writing the prompt. Build a test set that includes routine cases, ambiguous cases, missing context, adversarial wording, and examples from different customer segments. Measure accuracy by class, not only as a single average, because a model that performs well overall may still fail on a small but important group.
Next, compare Jev with a rules baseline and the model currently used in production. Track latency, total cost, calibration, escalation rate, and the downstream business result. Version prompts and thresholds, keep a record of inputs and outputs where privacy rules permit it, and deploy behind a feature flag. Jev's sudden popularity is interesting, but popularity is not proof that it fits a particular system. The winning implementation will be the one that treats the model as a measurable component, not as magic.