Eleven v4 is an AI Audio Generators tool. Advanced text-to-speech model that creates expressive, emotionally rich voice audio. Key features include Expressive Speech Generation, Voice Cloning Technology, and Turbo Variant for Real-Time Use. Best for content creators, filmmakers and video editors and software developers and engineers.
About Eleven v4
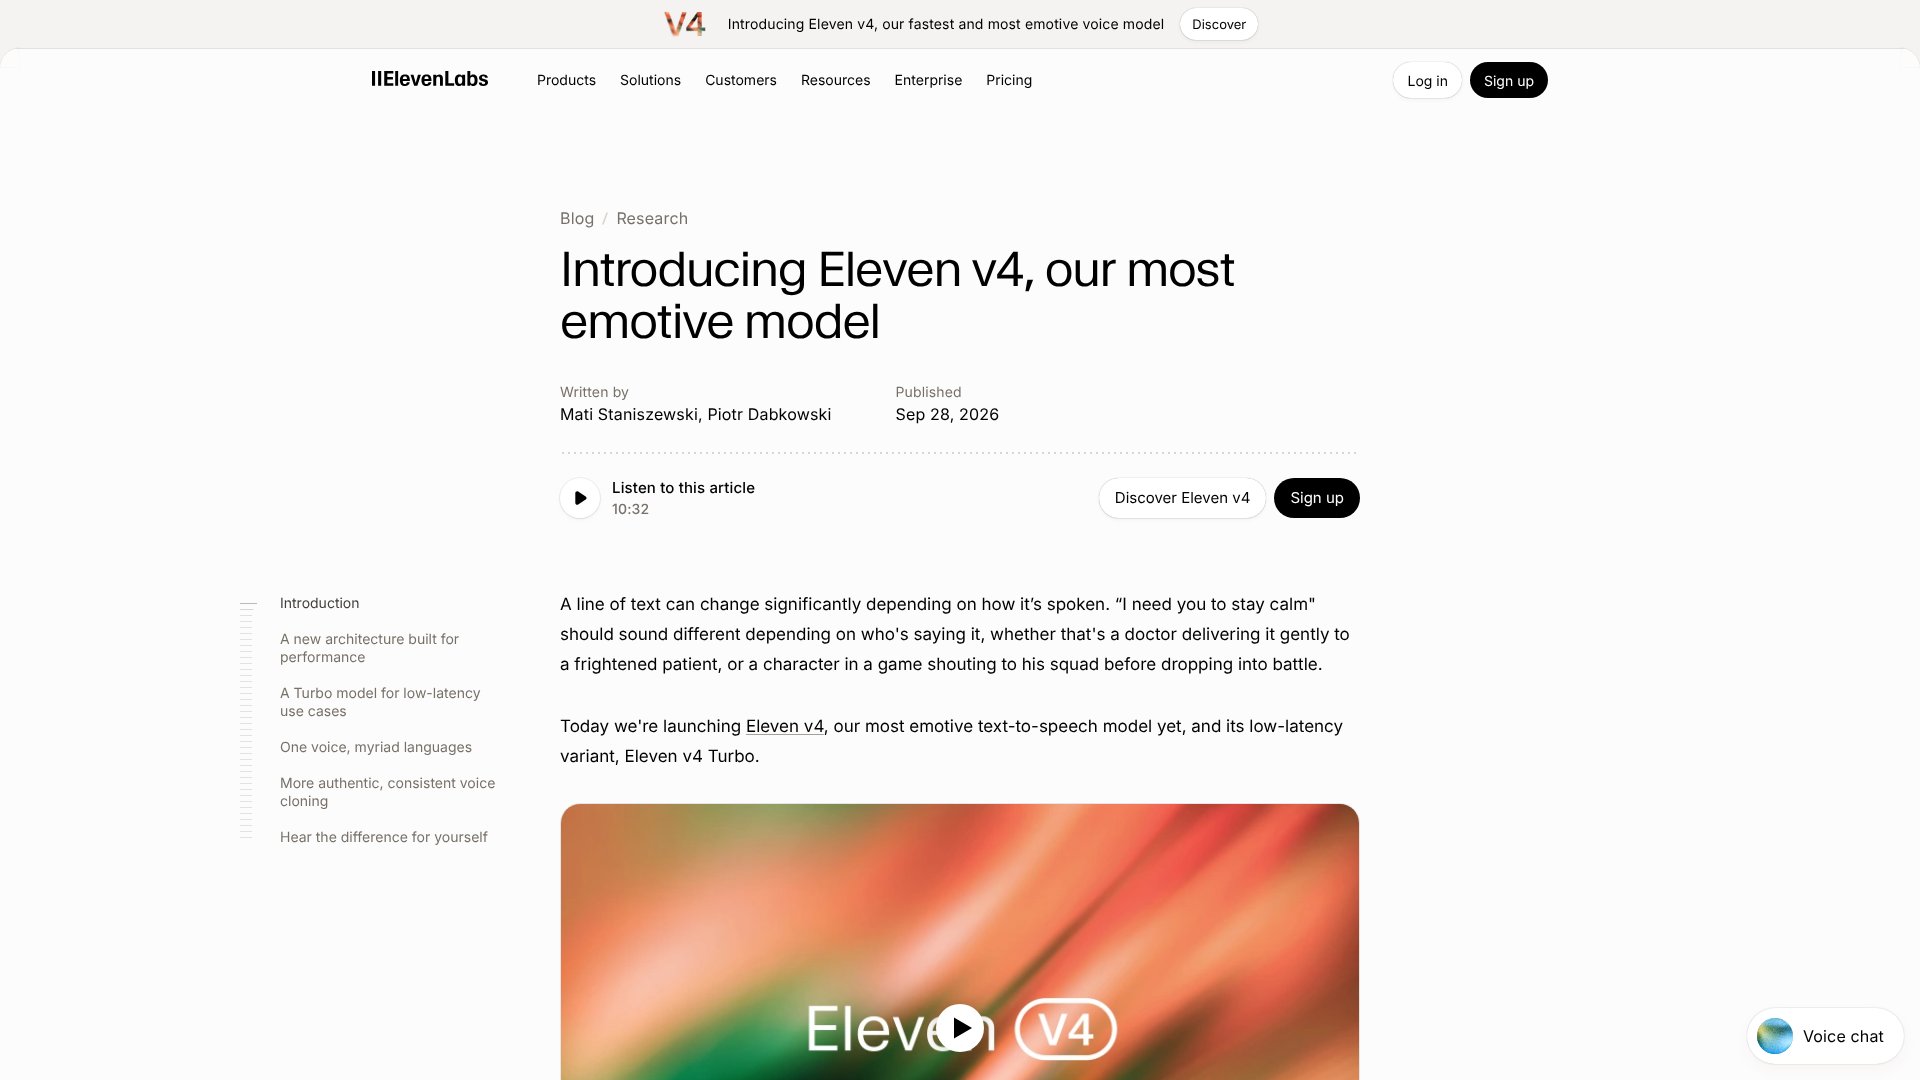
Eleven v4 is ElevenLabs' most advanced text-to-speech model that interprets tone, pacing, emotion, and context to generate dramatic, tender, urgent, or conversational speech. It supports 90+ languages with voice cloning from just 10 seconds of audio.
Key Features
Expressive Speech Generation.
Voice Cloning Technology.
Turbo Variant for Real-Time Use.
Multi-Language Support.
Audio Tags and Fine Control.
Multi-Speaker Dialogue.
Frequently Asked Questions
Eleven v4 is ElevenLabs' latest and most advanced text-to-speech model, launched in September 2026. It's built on an entirely new architecture designed to interpret tone, pacing, emotion, and context from text. The model generates expressive speech that can sound dramatic, tender, urgent, or conversational while maintaining the speaker's identity across 90+ languages.
Eleven v4 Turbo has a median inference latency of approximately 100 milliseconds and a median time to first speech of around 150 milliseconds. This makes it faster than the average pause between two people talking, which is why it's built for real-time applications like conversational AI agents and live customer interactions.
Eleven v4 is available on ElevenLabs' credit-based pricing plans, starting with a free tier that includes 10,000 credits per month. Paid plans range from Starter at $6 per month with 30,000 credits to Business at $990 per month with 6 million credits. The Creator plan at $22 per month is popular for individual content creators.
You can create audiobooks, character voiceovers for games and animation, marketing content, podcasts, video narration, multi-speaker dialogue, and conversational AI agents. The model handles long-form content up to 10,000 characters per generation and supports voice cloning, making it suitable for any project where delivery and emotion matter.