Gemma 4 12B is a Large Language Models (LLMs) tool. An encoder-free multimodal AI model that runs locally on laptops with 16GB RAM. Key features include Encoder-Free Architecture, Native Audio Processing, and Runs on Consumer Hardware. Best for software developers and engineers, data scientists and analysts and scientists and researchers.
About Gemma 4 12B
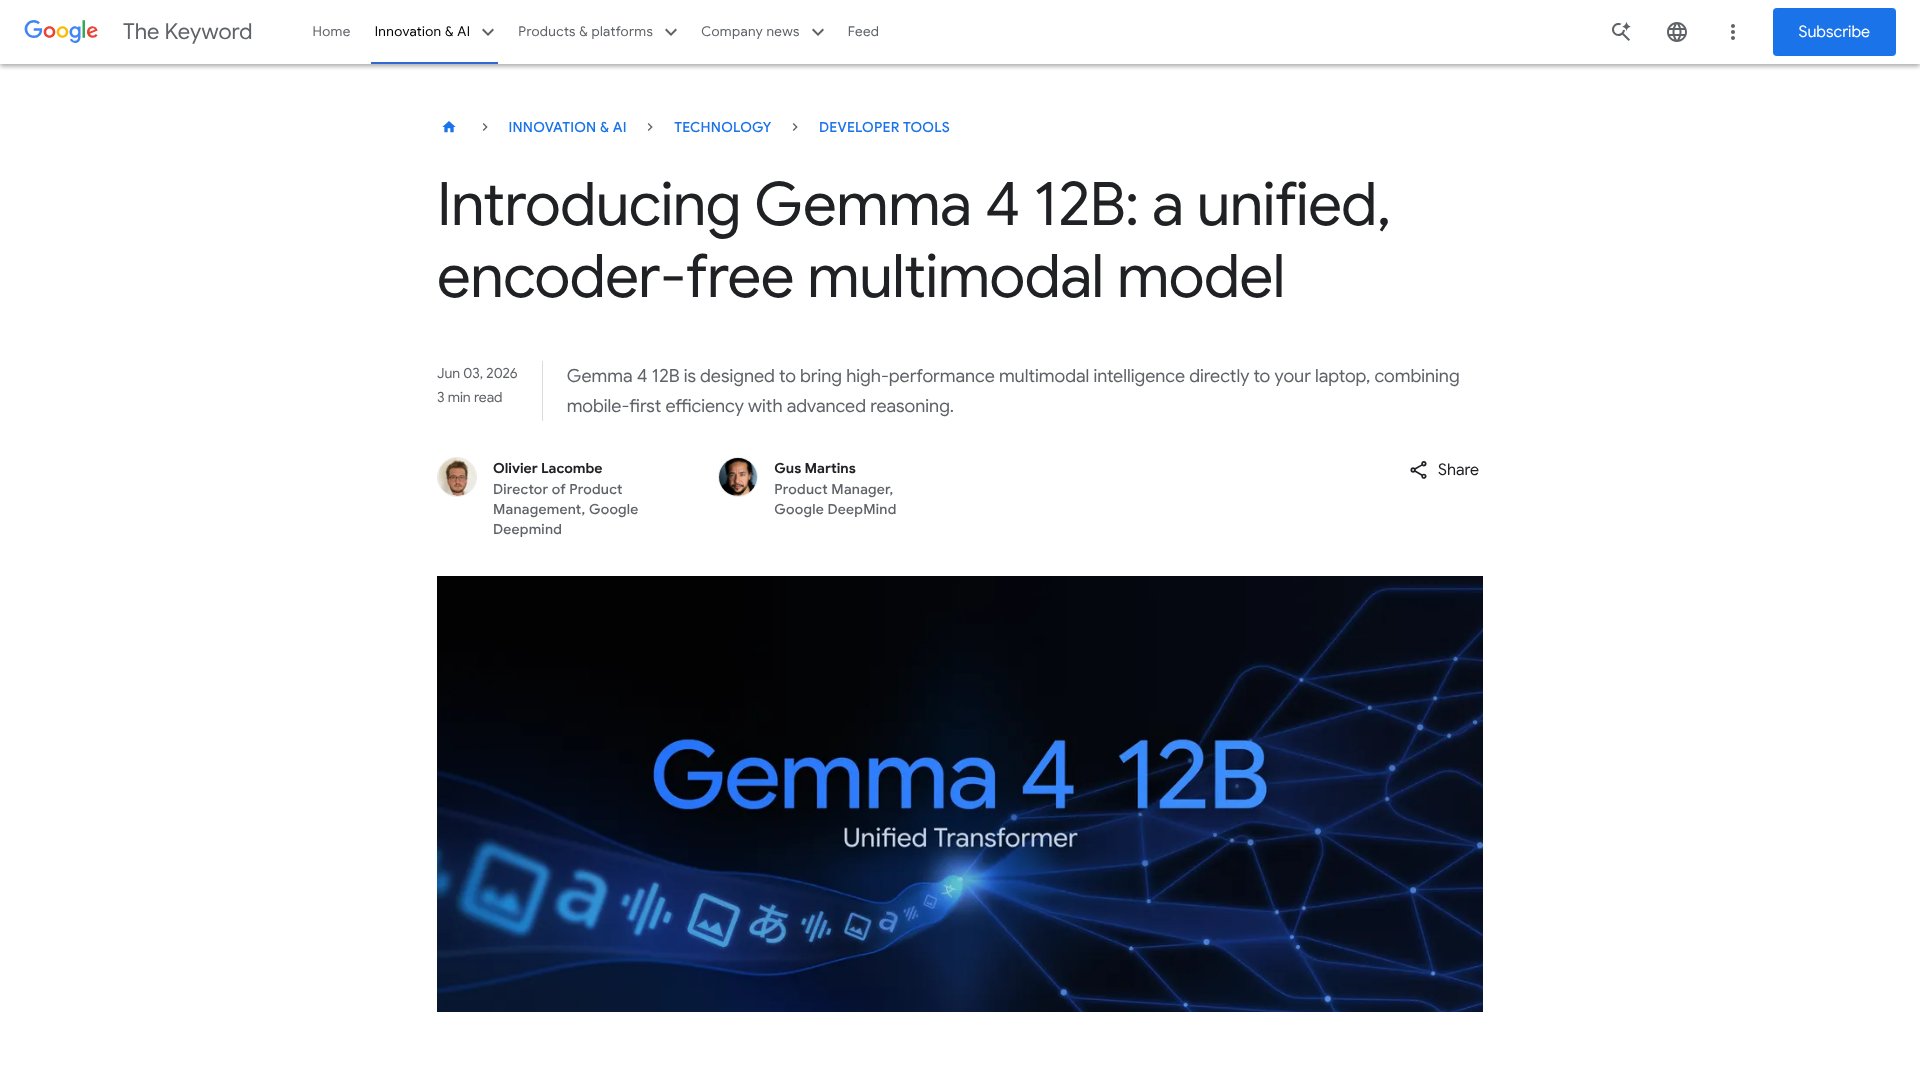
Gemma 4 12B is an open-source multimodal language model from Google DeepMind that processes text, images, video, and audio natively on consumer laptops. It runs on just 16GB of RAM and delivers performance close to larger models while using an encoder-free architecture.
Key Features
Encoder-Free Architecture.
Native Audio Processing.
Runs on Consumer Hardware.
Multimodal Input Support.
Apache 2.0 License.
Agentic Workflows.
Frequently Asked Questions
Gemma 4 12B uses an encoder-free architecture that processes vision and audio directly in the language model backbone, without separate encoders. This makes it faster and more memory-efficient than traditional multimodal models while maintaining strong performance.
Yes. Gemma 4 12B is designed to run locally on consumer laptops with 16GB of VRAM or unified memory. It works on modern Windows machines and Apple MacBooks without needing cloud infrastructure or powerful server hardware.
Yes. Gemma 4 12B is released under the Apache 2.0 license, which means you can use it for commercial purposes, modify it, and deploy it in your products without licensing fees or usage restrictions.
Gemma 4 12B can handle automatic speech recognition, video analysis, document processing, code generation, multi-step reasoning, and agentic workflows. It processes text, images, audio, and video natively, making it suitable for diverse multimodal applications.